Building a Custom Hash Map from Scratch: Collision Resolution, Robin Hood Hashing, and Dynamic Rehashing
Build a high-performance hash map from first principles in C and Rust. Explore hash functions (MurmurHash3, FNV-1a), collision resolution strategies (Separate Chaining vs Open Addressing), Robin Hood hashing, load factors, and dynamic resizing.
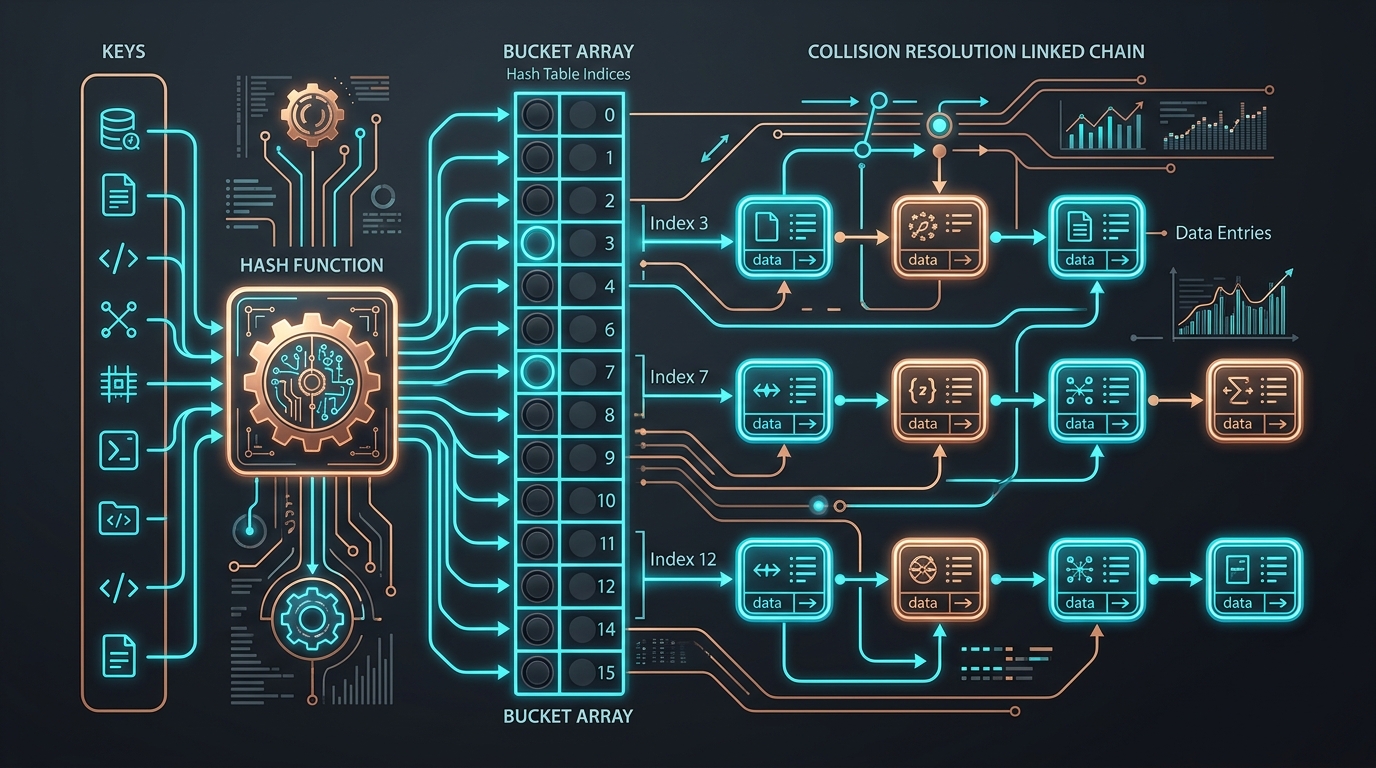
Hash maps (dictionaries or associative arrays) are the workhorse data structure of modern software engineering. Every time you query an in-memory key-value cache, index records, or access object properties in JavaScript or Python, an underlying hash table performs the heavy lifting.
While software engineers rely on std::unordered_map (C++), HashMap (Rust), or dict (Python) daily, few understand the low-level systems mechanics that make them fast: How does a hash function distribute entropy evenly? What happens during a hash collision? Why has modern systems programming shifted away from linked-list Separate Chaining toward cache-friendly Open Addressing and Robin Hood Hashing?
This comprehensive guide builds a production-grade, cache-conscious Hash Map from scratch, exploring hash functions, collision resolution strategies, tombstones, and dynamic rehashing.
💡 Key Takeaways (TL;DR)#
- Hash Function Contract: Maps arbitrary keys (strings, structs) to a uniform 64-bit integer distribution with minimal clustering (e.g., FNV-1a, MurmurHash3, SipHash).
- Separate Chaining vs. Open Addressing: Separate Chaining (linked lists in buckets) suffers from CPU cache misses. Modern high-performance hash maps use Open Addressing (Linear Probing, Robin Hood, or Swiss Tables) to store entries in a flat contiguous array.
- Robin Hood Hashing: Reduces lookup variance by "stealing from the rich and giving to the poor"—displacing existing entries with smaller probe sequence lengths (PSL) to keep average probe counts near 1.0.
- Load Factor Threshold: When
Load Factor = Elements / Capacity >= 0.75, the hash map must allocate a 2x larger array and rehash all keys to prevent catastrophic cluster degradation. - Tombstone Markers: In Open Addressing, deleting an entry requires a
TOMBSTONEmarker so ongoing search probe chains are not prematurely broken.
1. The Anatomy of a Hash Map#
At its core, a hash map converts an arbitrary key into an array index through a mathematical pipeline:
1. The Hash Function (FNV-1a)#
A cryptographic hash function (like SHA-256) is unnecessarily slow for in-memory lookups. High-performance hash maps prefer non-cryptographic hashes with high avalanche characteristics (every 1-bit change flips ~50% of output bits).
// FNV-1a 64-bit Hash Implementation in Rust
pub fn fnv1a_hash(data: &[u8]) -> u64 {
    const FNV_OFFSET_BASIS: u64 = 0xcbf29ce484222325;
    const FNV_PRIME: u64 = 0x100000001b3;

    let mut hash = FNV_OFFSET_BASIS;
    for &byte in data {
        hash ^= byte as u64;
        hash = hash.wrapping_mul(FNV_PRIME);
    }
    hash
}
2. Collision Resolution: Chaining vs. Open Addressing#
When two distinct keys produce the same array index (hash(K1) % C == hash(K2) % C), a hash collision occurs.
Comparison Matrix#
| Strategy | Memory Layout | CPU Cache Locality | Deletion Complexity | Behavior at High Load Factor |
|---|---|---|---|---|
| Separate Chaining | Array of Linked List pointers | Poor (Pointer chasing in heap) | Simple (Unlink node) | Degrades gracefully to O(K) |
| Linear Probing | Single contiguous array | Excellent (Sequential cache lines) | Requires Tombstones | Severe clustering (Primary clustering) |
| Robin Hood Hashing | Contiguous array with PSL tags | Excellent | Low variance lookups | Highly predictable lookups up to 90% load |
| Swiss Tables (SIMD) | Control bytes + Packed slots | State-of-the-Art (Parallel SIMD match) | Fast bitwise deletion | Peak modern standard (Rust stdlib / Abseil) |
3. The Power of Robin Hood Hashing#
In standard Linear Probing, if slot i is full, you simply try i+1, i+2, .... This leads to primary clustering: long runs of occupied slots that cause search times to spiral.
Robin Hood Hashing tracks the Probe Sequence Length (PSL)—how far each entry has traveled from its ideal hashed bucket:
Rule of Robin Hood Hashing:
When inserting a new key with probe count P_new into an occupied slot with existing probe count P_existing:
If P_new > P_existing:
    Swap the elements!
    The new key takes the slot (rich given to poor), and we continue inserting the displaced element.
Why Robin Hood Hashing Wins#
- Low Variance in Lookups: No single key gets stuck with an extreme probe distance (
PSL > 20). - Early Search Termination: When searching for a key, if you encounter an occupied slot whose
PSL < current search PSL, you can terminate immediately with a negative result (the key cannot exist past that point).
4. Complete Implementation from Scratch in Rust#
Here is a functional, generic Robin Hood Hash Map implementation with dynamic rehashing:
use std::mem;

const INITIAL_CAPACITY: usize = 8;
const MAX_LOAD_FACTOR: f64 = 0.70;

#[derive(Clone, Debug)]
struct Bucket<K, V> {
    key: K,
    val: V,
    psl: usize, // Probe Sequence Length
}

pub struct RobinHoodHashMap<K, V> {
    buckets: Vec<Option<Bucket<K, V>>>,
    size: usize,
}

impl<K: Eq + AsRef<[u8]> + Clone, V: Clone> RobinHoodHashMap<K, V> {
    pub fn new() -> Self {
        let mut buckets = Vec::with_capacity(INITIAL_CAPACITY);
        for _ in 0..INITIAL_CAPACITY {
            buckets.push(None);
        }
        Self { buckets, size: 0 }
    }

    fn hash_key(&self, key: &K, capacity: usize) -> usize {
        // Simple FNV-1a hash mod power-of-two capacity
        const FNV_OFFSET: u64 = 0xcbf29ce484222325;
        const FNV_PRIME: u64 = 0x100000001b3;
        let mut hash = FNV_OFFSET;
        for &b in key.as_ref() {
            hash ^= b as u64;
            hash = hash.wrapping_mul(FNV_PRIME);
        }
        (hash as usize) & (capacity - 1)
    }

    pub fn insert(&mut self, key: K, val: V) {
        if (self.size + 1) as f64 / self.buckets.len() as f64 > MAX_LOAD_FACTOR {
            self.resize();
        }

        let mut incoming = Bucket { key, val, psl: 0 };
        let mut idx = self.hash_key(&incoming.key, self.buckets.len());
        let cap = self.buckets.len();

        loop {
            match &mut self.buckets[idx] {
                None => {
                    self.buckets[idx] = Some(incoming);
                    self.size += 1;
                    return;
                }
                Some(existing) if existing.key == incoming.key => {
                    existing.val = incoming.val; // Overwrite existing key
                    return;
                }
                Some(existing) => {
                    // Robin Hood condition: Steal from the rich
                    if incoming.psl > existing.psl {
                        mem::swap(existing, &mut incoming);
                    }
                    // Continue probing with displaced element
                    incoming.psl += 1;
                    idx = (idx + 1) & (cap - 1);
                }
            }
        }
    }

    pub fn get(&self, key: &K) -> Option<&V> {
        let cap = self.buckets.len();
        let mut idx = self.hash_key(key, cap);
        let mut psl = 0;

        loop {
            match &self.buckets[idx] {
                None => return None,
                Some(entry) => {
                    if &entry.key == key {
                        return Some(&entry.val);
                    }
                    // Early termination optimization
                    if psl > entry.psl {
                        return None;
                    }
                }
            }
            psl += 1;
            idx = (idx + 1) & (cap - 1);
        }
    }

    fn resize(&mut self) {
        let new_cap = self.buckets.len() * 2;
        let old_buckets = mem::replace(&mut self.buckets, (0..new_cap).map(|_| None).collect());
        self.size = 0;

        for bucket in old_buckets.into_iter().flatten() {
            self.insert(bucket.key, bucket.val);
        }
    }
}
5. Deletion Strategies & Tombstones#
In Open Addressing, simply setting a deleted slot to None breaks the chain for elements that collided past that slot!
If Slot 11 is cleared to empty None, searching for Key C checks Slot 10 (mismatch), checks Slot 11 (empty!), and concludes Key C does not exist—a silent corruption bug.
Solutions to Open Addressing Deletion#
- Tombstone Markers: Replace deleted slots with a special sentinel
TOMBSTONE. Searches continue through tombstones, but inserts can overwrite them. - Backward Shift Deletion (Robin Hood Optimization): Shift subsequent elements with
PSL > 0backward by 1 slot until an empty slot orPSL = 0element is encountered, avoiding tombstone clutter.
Frequently Asked Questions#
Why must hash map capacity always be a power of two?#
When capacity C = 2^k, computing the bucket index hash % C can be implemented as the bitwise operation hash & (C - 1). Bitwise AND takes a single clock cycle, whereas integer division takes 10–30 cycles on modern CPUs.
What is the difference between Robin Hood Hashing and Swiss Tables?#
Robin Hood hashing optimizes open addressing by equalizing probe lengths across all elements. Swiss Tables (developed by Google in Abseil and used in Rust's hashbrown) store 1-byte control metadata for 16 slots simultaneously, using SIMD (Single Instruction, Multiple Data) vector instructions to check 16 buckets in parallel in one CPU cycle.
What causes a HashDoS (Denial of Service) attack?#
If an attacker knows your hash function (e.g., deterministic FNV-1a without a secret seed), they can submit thousands of keys crafted to produce the exact same hash index. This forces lookups from O(1) into degenerate O(N) linear chains, freezing web servers. Modern production hash maps (like SipHash in Python and Rust) use randomized per-process seeds to defend against HashDoS.
Joey Jazwinski
Hi, I'm Joey — a software engineer building modern applications, exploring artificial intelligence, and sharing my journey through code. 🚀
Recommended Articles
View all posts →
Demystifying MongoDB Connection Strings: URI Parameters, Replica Sets, and TLS
A complete engineering guide to MongoDB connection URIs. Learn DNS SRV lookups, replica set topology discovery, write concerns, pool sizing, and TLS options.
How QR Codes Work Under the Hood: Reed-Solomon Error Correction, Mask Patterns, and Matrix Encodings
Explore the computer science and math behind Quick Response codes. Learn 1:1:3:1:1 finder patterns, Galois field error correction, mask formulas, and URI schemes.
Runtime Type Validation in TypeScript: Zod Architecture, Static Type Inference, and API Boundary Defense
Master runtime validation in TypeScript. Learn how Zod executes schema parsing, derives static types with z.infer, and protects API boundaries against invalid input.