Structured Outputs from LLMs: Enforcing Strict JSON Schemas, Grammar Sampling, and Function Calling
Master guaranteed JSON schemas and structured outputs with Large Language Models. Learn constrained decoding, grammar-guided sampling, Pydantic validation, and debug schema generation in real-time.
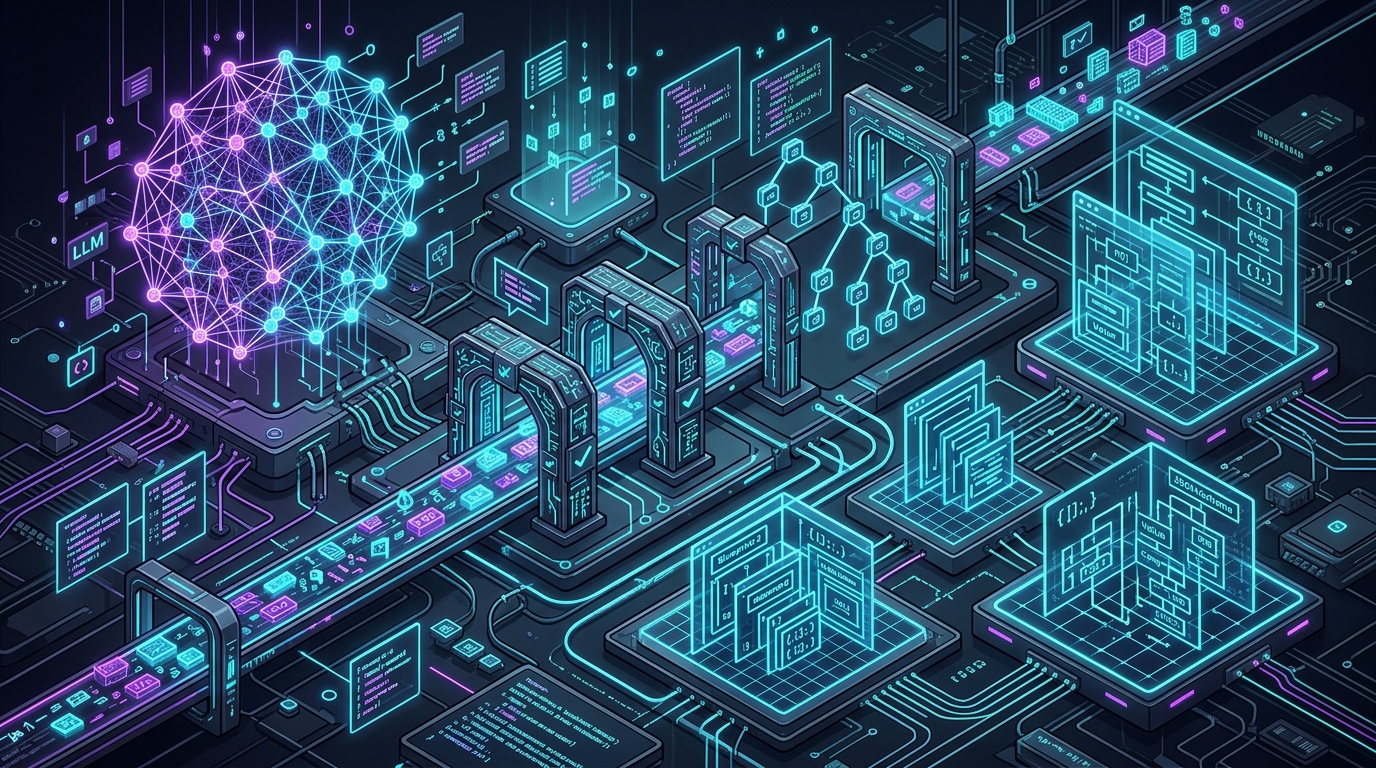
When building production AI agents, autonomous workflows, and data pipelines, raw natural language responses from Large Language Models (LLMs) are notoriously unreliable. A model might return markdown code blocks, omit required fields, hallucinate extra keys, or emit trailing commas that crash downstream JSON.parse() handlers.
In production engineering, you cannot rely on prompt engineering alone (like asking "Please respond only with valid JSON"). You need deterministic structured outputs guaranteed at the token generation level.
In this comprehensive tutorial, you will learn the exact mechanics of constrained decoding, grammar-guided sampling (CFGs), function calling architectures, schema validation strategies in Python and TypeScript, and how to test your schemas using interactive developer tools.
💡 Key Takeaways (TL;DR)#
- Constrained Decoding vs Prompting: Prompting asks the LLM nicely to format text. Constrained decoding (used by modern inference engines like vLLM, llama.cpp, and OpenAI Structured Outputs) modifies the model's logits during token sampling to make invalid syntax mathematically impossible.
- Context-Free Grammars (CFGs): Engines map a JSON Schema into a finite-state machine or grammar parser. At each step, tokens that violate the schema receive a logit mask of
-Infinity. - Schema Design Best Practices: Always set
additionalProperties: false, explicitly mark all fields in therequiredarray, and keep nesting depths reasonable to avoid latency spikes. - Validation Tooling: Combine Pydantic (Python) or Zod (TypeScript) on the application layer with engine-level schema enforcement for complete type safety.
- Interactive Playground: Design, validate, and inspect your schemas directly using the JSON to Schema Generator and JSON Prettifier.
1. The Core Problem: Why Plain Prompting Fails#
LLMs predict the next most probable token based on training distribution. When generating structured data without constraints, several failure modes occur:
- Markdown Wrapping: Models frequently wrap responses in
```json ... ```blocks, breaking direct API parsers. - Schema Drift: Optional fields randomly disappear or morph into unexpected types (e.g. an integer string
"42"instead of a number42). - Truncated Payloads: When context limits or max token budgets are reached mid-stream, the emitted JSON is unclosed and invalid.
- Hallucinated Attributes: Models inject unprompted explanatory keys or polite conversational commentary before the JSON body.
To solve this reliably in production, modern systems enforce constraints during token sampling.
2. How Constrained Sampling Works Under the Hood#
Constrained decoding operates directly inside the inference loop before softmax sampling.
The Step-by-Step Mechanism:#
- Schema Compilation: Your JSON Schema or regex pattern is compiled into a Context-Free Grammar (CFG) or Deterministic Finite Automaton (DFA).
- State Tracking: As the model generates characters, the grammar tracker maintains the current parsing state (e.g. "currently inside an open string key" or "expecting a colon after a key").
- Logit Masking: Before the model samples the next token, the engine identifies which tokens from the vocabulary would cause a syntax violation. The logit values for those illegal tokens are set to
-Infinity. - Guaranteed Valid Token: The model only samples from tokens that keep the JSON syntax and schema rules intact.
Because invalid paths are masked at each token step, the output is 100% syntactically valid JSON matching your schema definition without requiring retry loops.
3. Defining Bulletproof JSON Schemas#
When supplying a schema to structured output endpoints, modern APIs (such as OpenAI, Anthropic, Gemini, and Ollama) require strict schema compliance.
Here is a production-grade schema for extracting structured user sentiment and key entity tags:
{
  "type": "object",
  "properties": {
    "sentiment": {
      "type": "string",
      "enum": ["positive", "neutral", "negative"],
      "description": "The overall sentiment classification of the text."
    },
    "confidenceScore": {
      "type": "number",
      "description": "Confidence rating between 0.0 and 1.0."
    },
    "entities": {
      "type": "array",
      "items": {
        "type": "object",
        "properties": {
          "name": { "type": "string" },
          "category": {
            "type": "string",
            "enum": ["person", "organization", "location", "product"]
          }
        },
        "required": ["name", "category"],
        "additionalProperties": false
      },
      "description": "List of recognized named entities."
    },
    "summary": {
      "type": "string",
      "description": "One-sentence plain text summary."
    }
  },
  "required": ["sentiment", "confidenceScore", "entities", "summary"],
  "additionalProperties": false
}
⚠️ Critical Schema Rules:
additionalProperties: false: Required on all object schemas to prevent unexpected fields.- Explicit
requiredlist: Every property listed underpropertiesmust also be included in therequiredarray. If a field is optional, model it as a nullable type (e.g.type: ["string", "null"]).
4. Implementation in Python with Pydantic#
Using Pydantic with modern client libraries gives you compile-time type checking and runtime schema serialization:
from typing import List, Literal, Optional
from pydantic import BaseModel, Field
import openai

# 1. Define strict type schemas
class Entity(BaseModel):
    name: str
    category: Literal["person", "organization", "location", "product"]

class AnalysisResult(BaseModel):
    sentiment: Literal["positive", "neutral", "negative"]
    confidence_score: float = Field(ge=0.0, le=1.0)
    entities: List[Entity]
    summary: str

# 2. Invoke model with structured output parsing
client = openai.OpenAI()

completion = client.beta.chat.completions.parse(
    model="gpt-4o-mini",
    messages=[
        {"role": "system", "content": "You are a customer feedback analysis engine."},
        {"role": "user", "content": "Joey from Acme Corp loved the fast response times in San Francisco!"}
    ],
    response_format=AnalysisResult,
)

# 3. Access guaranteed typed attributes directly
result: AnalysisResult = completion.choices[0].message.parsed
print(f"Sentiment: {result.sentiment}")
print(f"Entities: {[e.name for e in result.entities]}")
5. Implementation in TypeScript with Zod#
In Node.js and Next.js environments, Zod paired with modern SDKs provides end-to-end type safety:
import { z } from 'zod';
import { zodResponseFormat } from 'openai/helpers/zod';
import OpenAI from 'openai';

const openai = new OpenAI();

// Define validation schema
const AnalysisSchema = z.object({
  sentiment: z.enum(['positive', 'neutral', 'negative']),
  confidenceScore: z.number().min(0).max(1),
  entities: z.array(
    z.object({
      name: z.string(),
      category: z.enum(['person', 'organization', 'location', 'product']),
    })
  ),
  summary: z.string(),
});

type AnalysisResult = z.infer<typeof AnalysisSchema>;

async function analyzeFeedback(text: string): Promise<AnalysisResult> {
  const completion = await openai.beta.chat.completions.parse({
    model: 'gpt-4o-mini',
    messages: [
      { role: 'system', content: 'Extract structured analytics from user messages.' },
      { role: 'user', content: text },
    ],
    response_format: zodResponseFormat(AnalysisSchema, 'analysis_result'),
  });

  const parsed = completion.choices[0].message.parsed;
  if (!parsed) throw new Error('Failed to parse structured output.');
  return parsed;
}
6. Interactive Developer Tool Integration#
Need to convert raw JSON payloads into production-ready schemas, test validation rules, or format complex API responses? Use the built-in developer tools:
- JSON Schema Generator & Inspector: Automatically generate strict JSON Schemas from raw sample objects with one click.
- JSON Prettifier & Formatter: Clean, validate, and inspect your API payloads.
- JSON to SQL Insert Converter: Transform structured LLM records directly into relational database tables.
7. Production Troubleshooting & Edge Cases#
| Challenge | Root Cause | Solution |
|---|---|---|
| Increased First-Token Latency | Complex grammar graphs take time to compile on first request. | Cache grammar automata across requests; keep nesting under 4 levels. |
| Model Refusal | Strict schemas may conflict with system guardrails or safety filters. | Verify prompts don't trigger policy filters; add fallback handlers. |
| Enum Mismatch | Target categories evolve over time in production. | Keep enums versioned; use integration test suites with synthetic inputs. |
| High Output Token Usage | Verbose JSON keys repeat on every record in large arrays. | Use compact key names or tabular formats for large batches. |
Constrained structured outputs transform probabilistic LLMs into reliable backend components. By letting the inference engine enforce syntax at the token layer, your systems gain deterministic guarantees and zero-retry parsing reliability.
Joey Jazwinski
Hi, I'm Joey — a software engineer building modern applications, exploring artificial intelligence, and sharing my journey through code. 🚀
Recommended Articles
View all posts →
Understanding JSON Web Tokens (JWT): Structure, Security Vulnerabilities, and Debugging Guide
Master JSON Web Tokens (JWT) in modern authentication. Learn the anatomy of Headers, Payloads, and Signatures (HMAC vs RSA/ECDSA), prevent security pitfalls like algorithm confusion, and debug tokens in real-time.
XML Sitemaps Explained: Protocol Standards, Large-Scale Architecture, and Generator Guide
Master XML sitemaps for modern web indexing. Learn sitemap protocol standards, sitemap index splitting rules, image/news extensions, Next.js automation, and generate valid sitemaps with free developer tools.
Building a Custom Hash Map from Scratch: Collision Resolution, Robin Hood Hashing, and Dynamic Rehashing
Build a high-performance hash map from first principles in C and Rust. Explore hash functions (MurmurHash3, FNV-1a), collision resolution strategies (Separate Chaining vs Open Addressing), Robin Hood hashing, load factors, and dynamic resizing.